Tuesday, April 18, 2017

MLHardware: Understanding and Optimizing Asynchronous Low-Precision Stochastic Gradient Descent / WRPN: Training and Inference using Wide Reduced-Precision Networks

( Personal message: I will at ICLR next week, let's grab some coffee if you are there. )


As ML is becoming more and more important, the hardware architecture on which it runs needs to change as well. These changes in turns are wholly dependent on a number of trade-offs. Today, we have two such studies, one on the quantization issues in neural networks and another one on the influence of low precision on Stochastic Gradient Descent (something we already seen for  gradient descent )

For computer vision applications, prior works have shown the efficacy of reducing the numeric precision of model parameters (network weights) in deep neural networks but also that reducing the precision of activations hurts model accuracy much more than reducing the precision of model parameters. We study schemes to train networks from scratch using reduced-precision activations without hurting the model accuracy. We reduce the precision of activation maps (along with model parameters) using a novel quantization scheme and increase the number of filter maps in a layer, and find that this scheme compensates or surpasses the accuracy of the baseline full-precision network. As a result, one can significantly reduce the dynamic memory footprint, memory bandwidth, computational energy and speed up the training and inference process with appropriate hardware support. We call our scheme WRPN - wide reduced-precision networks. We report results using our proposed schemes and show that our results are better than previously reported accuracies on ILSVRC-12 dataset while being computationally less expensive compared to previously reported reduced-precision networks.


Stochastic gradient descent (SGD) is one of the most popular numerical algorithms used in machine learning and other domains. Since this is likely to continue for the foreseeable future, it is important to study techniques that can make it run fast on parallel hardware. In this paper, we provide the first analysis of a technique called BUCKWILD! that uses both asynchronous execution and low-precision computation. We introduce the DMGC model, the first conceptualization of the parameter space that exists when implementing low-precision SGD, and show that it provides a way to both classify these algorithms and model their performance. We leverage this insight to propose and analyze techniques to improve the speed of low-precision SGD. First, we propose software optimizations that can increase throughput on existing CPUs by up to 11×. Second, we propose architectural changes, including a new cache technique we call an obstinate cache, that increase throughput beyond the limits of current-generation hardware. We also implement and analyze low-precision SGD on the FPGA, which is a promising alternative to the CPU for future SGD systems.


Join the CompressiveSensing subreddit or the Google+ Community or the Facebook page and post there !
Liked this entry ? subscribe to Nuit Blanche's feed, there's more where that came from. You can also subscribe to Nuit Blanche by Email, explore the Big Picture in Compressive Sensing or the Matrix Factorization Jungle and join the conversations on compressive sensing, advanced matrix factorization and calibration issues on Linkedin.

Monday, April 17, 2017

F2F: A Library For Fast Kernel Expansions

( Personal message: I will at ICLR next week, let's grab some coffee if you are there. )

F2F is a C++ library for large-scale machine learning. It contains a CPU optimized implementation of the Fastfood algorithm, that allows the computation of approximated kernel expansions in loglinear time. The algorithm requires to compute the product of Walsh-Hadamard Transform (WHT) matrices. A cache friendly SIMD Fast Walsh-Hadamard Transform (FWHT) that achieves compelling speed and outperforms current state-of-the-art methods has been developed. F2F allows to obtain non-linear classification combining Fastfood and a linear classifier.
I am told by one of the author that the library should be out at some point in time.


Join the CompressiveSensing subreddit or the Google+ Community or the Facebook page and post there !

Understanding Shallower Networks

We may need to Understanding Deep Neural Networks but we also need to understand Shallower networks


Empirical risk minimization (ERM) is ubiquitous in machine learning and underlies most supervised learning methods. While there has been a large body of work on algorithms for various ERM problems, the exact computational complexity of ERM is still not understood. We address this issue for multiple popular ERM problems including kernel SVMs, kernel ridge regression, and training the final layer of a neural network. In particular, we give conditional hardness results for these problems based on complexity-theoretic assumptions such as the Strong Exponential Time Hypothesis. Under these assumptions, we show that there are no algorithms that solve the aforementioned ERM problems to high accuracy in sub-quadratic time. We also give similar hardness results for computing the gradient of the empirical loss, which is the main computational burden in many non-convex learning tasks.


Remarkable success of deep neural networks has not been easy to analyze theoretically. It has been particularly hard to disentangle relative significance of architecture and optimization in achieving accurate classification on large datasets. On the flip side, shallow methods have encountered obstacles in scaling to large data, despite excellent performance on smaller datasets, and extensive theoretical analysis. Practical methods, such as variants of gradient descent used so successfully in deep learning, seem to perform below par when applied to kernel methods. This difficulty has sometimes been attributed to the limitations of shallow architecture.
In this paper we identify a basic limitation in gradient descent-based optimization in conjunctions with smooth kernels. An analysis demonstrates that only a vanishingly small fraction of the function space is reachable after a fixed number of iterations drastically limiting its power and resulting in severe over-regularization. The issue is purely algorithmic, persisting even in the limit of infinite data.
To address this issue, we introduce EigenPro iteration, based on a simple preconditioning scheme using a small number of approximately computed eigenvectors. It turns out that even this small amount of approximate second-order information results in significant improvement of performance for large-scale kernel methods. Using EigenPro in conjunction with stochastic gradient descent we demonstrate scalable state-of-the-art results for kernel methods on a modest computational budget.
Finally, these results indicate a need for a broader computational perspective on modern large-scale learning to complement more traditional statistical and convergence analyses. In particular, systematic analysis concentrating on the approximation power of algorithms with a fixed computation budget will lead to progress both in theory and practice.


Join the CompressiveSensing subreddit or the Google+ Community or the Facebook page and post there !

Friday, April 14, 2017

Understanding Deep Neural Networks; Opening the Black Box, Energy Propagation in DNNs, Exploring loss function topology

Today, we have three papers trying to explain why deep neural networks work.  From the first paper:
"In our experiments, most of the optimization epochs are spent on compressing the internal representations under the training error constraint. This compression occurs by the SGD without any other explicit regularization or sparsity, and - we believe - is largely responsible for the absence of overfitting in DL. This observation also suggests that there are many (exponential in the number of weights) different randomized networks with essentially optimal performance. "


Despite their great success, there is still no comprehensive theoretical understanding of learning with Deep Neural Networks (DNNs) or their inner organization. Previous work [Tishby & Zaslavsky (2015)] proposed to analyze DNNs in the Information Plane; i.e., the plane of the Mutual Information values that each layer preserves on the input and output variables. They suggested that the goal of the network is to optimize the Information Bottleneck (IB) tradeoff between compression and prediction, successively, for each layer.
In this work we follow up on this idea and demonstrate the effectiveness of the Information-Plane visualization of DNNs. We first show that the stochastic gradient descent (SGD) epochs have two distinct phases: fast empirical error minimization followed by slow representation compression, for each layer. We then argue that the DNN layers end up very close to the IB theoretical bound, and present a new theoretical argument for the computational benefit of the hidden layers.


Many practical machine learning tasks employ very deep convolutional neural networks. Such large depths pose formidable computational challenges in training and operating the network. It is therefore important to understand how many layers are actually needed to have most of the input signal's features be contained in the feature vector generated by the network. This question can be formalized by asking how quickly the energy contained in the feature maps decays across layers. In addition, it is desirable that none of the input signal's features be "lost" in the feature extraction network or, more formally, we want energy conservation in the sense of the energy contained in the feature vector being proportional to that of the corresponding input signal. This paper establishes conditions for energy conservation for a wide class of deep convolutional neural networks and characterizes corresponding feature map energy decay rates. Specifically, we consider general scattering networks, and find that under mild analyticity and high-pass conditions on the filters (which encompass, inter alia, various constructions of Weyl-Heisenberg filters, wavelets, ridgelets, (α)-curvelets, and shearlets) the feature map energy decays at least polynomially fast. For broad families of wavelets and Weyl-Heisenberg filters, the guaranteed decay rate is shown to be exponential. Our results yield handy estimates of the number of layers needed to have at least ((1−ε)⋅100)% of the input signal energy be contained in the feature vector.

Exploring loss function topology with cyclical learning rates by Leslie N. Smith, Nicholay Topin
We present observations and discussion of previously unreported phenomena discovered while training residual networks. The goal of this work is to better understand the nature of neural networks through the examination of these new empirical results. These behaviors were identified through the application of Cyclical Learning Rates (CLR) and linear network interpolation. Among these behaviors are counterintuitive increases and decreases in training loss and instances of rapid training. For example, we demonstrate how CLR can produce greater testing accuracy than traditional training despite using large learning rates. Files to replicate these results are available at this https URL


Join the CompressiveSensing subreddit or the Google+ Community or the Facebook page and post there !
Liked this entry ? subscribe to Nuit Blanche's feed, there's more where that came from. You can also subscribe to Nuit Blanche by Email, explore the Big Picture in Compressive Sensing or the Matrix Factorization Jungle and join the conversations on compressive sensing, advanced matrix factorization and calibration issues on Linkedin.

Thursday, April 13, 2017

In-Datacenter Performance Analysis of a Tensor Processing Unit​ (TM)

Norm Jouppi mentioned it in a Google blog entry a few days. He and his team have released some information about the TPU. This is very interesting because of how algorithms are changing hardware. Sure enough we know that NVIDIA has shifted its architecture to follow the successful Deep Neural networks development (and continues to do so) but when Google announced the TPU last year one could only wonder what they would be doing better than a chip maker.    wrote about this question in  Does Google’s TPU Investment Make Sense Going Forward? but I believe he misses the point entirely.

That point was made abundantly clear in a Wired article:
It’s not used to train the neural network beforehand. But as Jouppi explains, even that still saves the company quite a bit. It didn’t have to build, say, an extra 15 data centers. 
The reason Google did not wait for NVIDIA's architecture to change or for Moore's law to kick in (that is using OPM to do the work) is mostly because that hardware technology effort spare them a few bucks. It all comes down to the fact that we are all collectively not fast enough to make sense of data.

Here is Norm et al's paper:  In-Datacenter Performance Analysis of a Tensor Processing Unit​ (TM) by Norman P. Jouppi, Cliff Young, Nishant Patil, David Patterson, Gaurav Agrawal, Raminder Bajwa, Sarah Bates, Suresh Bhatia, Nan Boden, Al Borchers, Rick Boyle, Pierre-luc Cantin, Clifford Chao, Chris Clark, Jeremy Coriell, Mike Daley, Matt Dau, Jeffrey Dean, Ben Gelb, Tara Vazir Ghaemmaghami, Rajendra Gottipati, William Gulland, Robert Hagmann, C. Richard Ho, Doug Hogberg, John Hu, Robert Hundt, Dan Hurt, Julian Ibarz, Aaron Jaffey, Alek Jaworski, Alexander Kaplan, Harshit Khaitan, Andy Koch, Naveen Kumar, Steve Lacy, James Laudon, James Law, Diemthu Le, Chris Leary, Zhuyuan Liu, Kyle Lucke, Alan Lundin, Gordon MacKean, Adriana Maggiore, Maire Mahony, Kieran Miller, Rahul Nagarajan, Ravi Narayanaswami, Ray Ni, Kathy Nix, Thomas Norrie, Mark Omernick, Narayana Penukonda, Andy Phelps, Jonathan Ross, Matt Ross, Amir Salek, Emad Samadiani, Chris Severn, Gregory Sizikov, Matthew Snelham, Jed Souter, Dan Steinberg, Andy Swing, Mercedes Tan, Gregory Thorson, Bo Tian, Horia Toma, Erick Tuttle, Vijay Vasudevan, Richard Walter, Walter Wang, Eric Wilcox, and Doe Hyun Yoon

Many architects believe that major improvements in cost-energy-performance must now come from domain-specific hardware. This paper evaluates a custom ASIC—called a ​Tensor Pro​cessing Unit (TPU)— deployed in datacenters since 2015 that accelerates the inference phase of neural networks (NN). The heart of the TPU is a 65,536 8-bit MAC matrix multiply unit that offers a peak throughput of 92 TeraOps/second (TOPS) and a large (28 MiB) software-managed on-chip memory. The TPU’s deterministic execution model is a better match to the 99th-percentile response-time requirement of our NN applications than are the time-varying optimizations of CPUs and GPUs (caches, out-of-order execution, multithreading, multiprocessing, prefetching, ...) that help average throughput more than guaranteed latency. The lack of such features helps explain why, despite having myriad MACs and a big memory, the TPU is relatively small and low power. We compare the TPU to a server-class Intel Haswell CPU and an Nvidia K80 GPU, which are contemporaries deployed in the same datacenters. Our workload, written in the high-level TensorFlow framework, uses production NN applications (MLPs, CNNs, and LSTMs) that represent 95% of our datacenters’ NN inference demand. Despite low utilization for some applications, the TPU is on average about 15X - 30X faster than its contemporary GPU or CPU, with TOPS/Watt about 30X - 80X higher. Moreover, using the GPU’s GDDR5 memory in the TPU would triple achieved TOPS and raise TOPS/Watt to nearly 70X the GPU and 200X the CPU.


Join the CompressiveSensing subreddit or the Google+ Community or the Facebook page and post there !
Liked this entry ? subscribe to Nuit Blanche's feed, there's more where that came from. You can also subscribe to Nuit Blanche by Email, explore the Big Picture in Compressive Sensing or the Matrix Factorization Jungle and join the conversations on compressive sensing, advanced matrix factorization and calibration issues on Linkedin.

Wednesday, April 12, 2017

Two jobs, Research Scientists, NVIDIA

 This is new but since I did post a similar job opening for LightOn  in the realm of Machine Learning and Hardware, NVIDIA falls indeed in the same category:

Hi Igor,


Here are two great NVIDIA research roles, if you are interested in posting:

https://nvidia.wd5.myworkdayjobs.com/NVIDIAExternalCareerSite/job/US-CA-Santa-Clara/Research-Scientist--Machine-Learning-_JR1905891?shared_id=e998709d-4743-42e4-b2db-15a939ddd52a

https://nvidia.wd5.myworkdayjobs.com/NVIDIAExternalCareerSite/job/US-CA-Santa-Clara/Research-Scientist--Computer-Vision_JR1905140?shared_id=fe68f03b-f0d0-448a-829a-ba363b71f531

Let me know!

Best Regards,

Anita

Anita Rexinger| Talent Acquisition | NVIDIA Corporation


Join the CompressiveSensing subreddit or the Google+ Community or the Facebook page and post there !
Liked this entry ? subscribe to Nuit Blanche's feed, there's more where that came from. You can also subscribe to Nuit Blanche by Email, explore the Big Picture in Compressive Sensing or the Matrix Factorization Jungle and join the conversations on compressive sensing, advanced matrix factorization and calibration issues on Linkedin.

Highly Technical Reference Page: The Incredible PyTorch


Ritchie Ng put together The Incredible PyTorch, a curated list of tutorials, papers, projects, communities and more relating to PyTorch.It is here: https://github.com/ritchieng/the-incredible-pytorch
 
The reference page will be added to the list of Highly Technical Reference Pages


h/t Desernaut


Join the CompressiveSensing subreddit or the Google+ Community or the Facebook page and post there !
Liked this entry ? subscribe to Nuit Blanche's feed, there's more where that came from. You can also subscribe to Nuit Blanche by Email, explore the Big Picture in Compressive Sensing or the Matrix Factorization Jungle and join the conversations on compressive sensing, advanced matrix factorization and calibration issues on Linkedin.

Thursday, April 06, 2017

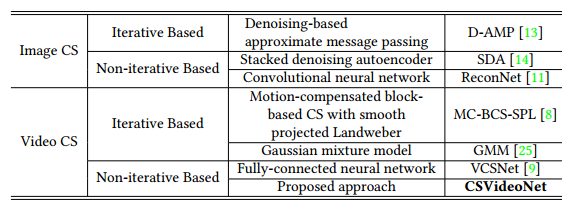
CSVideoNet: A Real-time End-to-end Learning Framework for High-frame-rate Video Compressive Sensing - implementation -

The Great Convergence continues: Compressive Sensing allowed the encoder to be non iterative and now a set of neural networks (CNNs, LSTMs) make the decoding also non iterative. Woohoo !


Fengbo who just received an interesting NSF award also sent me the following:


Dear Igor, 
Hope all is well.
Recently, we proposed a deep learning based encoding/decoding framework (CSVideoNet) for high-frame-rate video compressive sensing. We believe you and your blog’s readers would be interested in this research. The preview of the manuscript can be found here: https://arxiv.org/abs/1612.05203

CSVideoNet: A Real-time End-to-end Learning Framework for High-frame-rate Video Compressive Sensing by Kai Xu, Fengbo Ren
This paper addresses the real-time encoding-decoding problem for high-frame-rate video compressive sensing (CS). Unlike prior works that perform reconstruction using iterative optimization-based approaches, we propose a non-iterative model, named "CSVideoNet". CSVideoNet directly learns the inverse mapping of CS and reconstructs the original input in a single forward propagation. To overcome the limitations of existing CS cameras, we propose a multi-rate CNN and a synthesizing RNN to improve the trade-off between compression ratio (CR) and spatial-temporal resolution of the reconstructed videos. The experiment results demonstrate that CSVideoNet significantly outperforms the state-of-the-art approaches. With no pre/post-processing, we achieve 25dB PSNR recovery quality at 100x CR, with a frame rate of 125 fps on a Titan X GPU. Due to the feedforward and high-data-concurrency natures of CSVideoNet, it can take advantage of GPU acceleration to achieve three orders of magnitude speed-up over conventional iterative-based approaches. We share the source code at this https URL
Thanks,
================================
Fengbo​ Ren
Director, Parallel Systems and Computing Laboratory (PSCLab)
​Assistant Professor, School of Computing, Informatics, and Decision Systems Engineering (CIDSE)
Arizona State University (ASU)
========================​​=====​​===

Thanks Fengbo !


Join the CompressiveSensing subreddit or the Google+ Community or the Facebook page and post there !
Liked this entry ? subscribe to Nuit Blanche's feed, there's more where that came from. You can also subscribe to Nuit Blanche by Email, explore the Big Picture in Compressive Sensing or the Matrix Factorization Jungle and join the conversations on compressive sensing, advanced matrix factorization and calibration issues on Linkedin.

Tuesday, April 04, 2017

Improved Training of Wasserstein GANs - implementation -


Thanks Alex for the heads-up !


Generative Adversarial Networks (GANs) are powerful generative models, but suffer from training instability. The recently proposed Wasserstein GAN (WGAN) makes significant progress toward stable training of GANs, but can still generate low-quality samples or fail to converge in some settings. We find that these training failures are often due to the use of weight clipping in WGAN to enforce a Lipschitz constraint on the critic, which can lead to pathological behavior. We propose an alternative method for enforcing the Lipschitz constraint: instead of clipping weights, penalize the norm of the gradient of the critic with respect to its input. Our proposed method converges faster and generates higher-quality samples than WGAN with weight clipping. Finally, our method enables very stable GAN training: for the first time, we can train a wide variety of GAN architectures with almost no hyperparameter tuning, including 101-layer ResNets and language models over discrete data.


Implementation is here: https://github.com/igul222/improved_wgan_training


Join the CompressiveSensing subreddit or the Google+ Community or the Facebook page and post there !

It's all about convolutions: YodaNN, TrueNorth computing, FPGAs and a comparison between HOG and CNNs on Hardware

After yesterday's Compressive Sensing Hardware, let us look at the recent hardware needed to speed up Deep Learning algorithms where convolutions are a bottelneck. The last paper is also a welcome addition to people wondering about the link between architectures based on DL and those based on computer vision features. Enjoy !


YodaNN: An Architecture for Ultra-Low Power Binary-Weight CNN Acceleration by Renzo Andri, Lukas Cavigelli, Davide Rossi, Luca Benini


Convolutional neural networks (CNNs) have revolutionized the world of computer vision over the last few years, pushing image classification beyond human accuracy. The computational effort of today's CNNs requires power-hungry parallel processors or GP-GPUs. Recent developments in CNN accelerators for system-on-chip integration have reduced energy consumption significantly. Unfortunately, even these highly optimized devices are above the power envelope imposed by mobile and deeply embedded applications and face hard limitations caused by CNN weight I/O and storage. This prevents the adoption of CNNs in future ultra-low power Internet of Things end-nodes for near-sensor analytics. Recent algorithmic and theoretical advancements enable competitive classification accuracy even when limiting CNNs to binary (+1/-1) weights during training. These new findings bring major optimization opportunities in the arithmetic core by removing the need for expensive multiplications, as well as reducing I/O bandwidth and storage. In this work, we present an accelerator optimized for binary-weight CNNs that achieves 1510 GOp/s at 1.2 V on a core area of only 1.33 MGE (Million Gate Equivalent) or 0.19 mm
2

and with a power dissipation of 895 {\mu}W in UMC 65 nm technology at 0.6 V. Our accelerator significantly outperforms the state-of-the-art in terms of energy and area efficiency achieving 61.2 TOp/s/W@0.6 V and 1135 GOp/s/MGE@1.2 V, respectively.


  Deep networks are now able to achieve human-level performance on a broad spectrum of recognition tasks. Independently, neuromorphic computing has now demonstrated unprecedented energy-efficiency through a new chip architecture based on spiking neurons, low precision synapses, and a scalable communication network. Here, we demonstrate that neuromorphic computing, despite its novel architectural primitives, can implement deep convolution networks that (i) approach state-of-the-art classification accuracy across eight standard datasets encompassing vision and speech, (ii) perform inference while preserving the hardware’s underlying energy-efficiency and high throughput, running on the aforementioned datasets at between 1,200 and 2,600 frames/s and using between 25 and 275 mW (effectively  superior to 6,000 frames/s per Watt), and (iii) can be specified and trained using backpropagation with the same ease-of-use as contemporary deep learning. This approach allows the algorithmic power of deep learning to be merged with the efficiency of neuromorphic processors, bringing the promise of embedded, intelligent, brain-inspired computing one step closer.


FPGA-based hardware accelerators for convolutional neural networks (CNNs) have obtained great attentions due to their higher energy efficiency than GPUs. However, it is challenging for FPGA-based solutions to achieve a higher throughput than GPU counterparts. In this paper, we demonstrate that FPGA acceleration can be a superior solution in terms of both throughput and energy efficiency when a CNN is trained with binary constraints on weights and activations. Specifically, we propose an optimized accelerator architecture tailored for bitwise convolution and normalization that features massive spatial parallelism with deep pipelines stages. Experiment results show that the proposed architecture is 8.3x faster and 75x more energy-efficient than a Titan X GPU for processing online individual requests (in small batch size). For processing static data (in large batch size), the proposed solution is on a par with a Titan X GPU in terms of throughput while delivering 9.5x higher energy efficiency.

Towards Closing the Energy Gap Between HOG and CNN Features for Embedded Vision by Amr Suleiman, Yu-Hsin Chen, Joel Emer, Vivienne Sze

Computer vision enables a wide range of applications in robotics/drones, self-driving cars, smart Internet of Things, and portable/wearable electronics. For many of these applications, local embedded processing is preferred due to privacy and/or latency concerns. Accordingly, energy-efficient embedded vision hardware delivering real-time and robust performance is crucial. While deep learning is gaining popularity in several computer vision algorithms, a significant energy consumption difference exists compared to traditional hand-crafted approaches. In this paper, we provide an in-depth analysis of the computation, energy and accuracy trade-offs between learned features such as deep Convolutional Neural Networks (CNN) and hand-crafted features such as Histogram of Oriented Gradients (HOG). This analysis is supported by measurements from two chips that implement these algorithms. Our goal is to understand the source of the energy discrepancy between the two approaches and to provide insight about the potential areas where CNNs can be improved and eventually approach the energy-efficiency of HOG while maintaining its outstanding performance accuracy.

 
Join the CompressiveSensing subreddit or the Google+ Community or the Facebook page and post there !
Liked this entry ? subscribe to Nuit Blanche's feed, there's more where that came from. You can also subscribe to Nuit Blanche by Email, explore the Big Picture in Compressive Sensing or the Matrix Factorization Jungle and join the conversations on compressive sensing, advanced matrix factorization and calibration issues on Linkedin.
Printfriendly